Failure watcher v1
BEHAVIOR-1K 2026 challenge, issue 72, PR 73, jobs Oct 18 to 19 HST
The watcher embeds 1 fps head and wrist frames with frozen SigLIP So400m and trains small heads that predict whether a run will succeed from the task and the frames so far. It covers 2,963 scored policy runs and 1,000 teleop demos. The result is mostly negative, because the frames barely beat what the task and the elapsed time already tell you.
Held-out instances
| predictor | 10% | 25% | 50% |
|---|---|---|---|
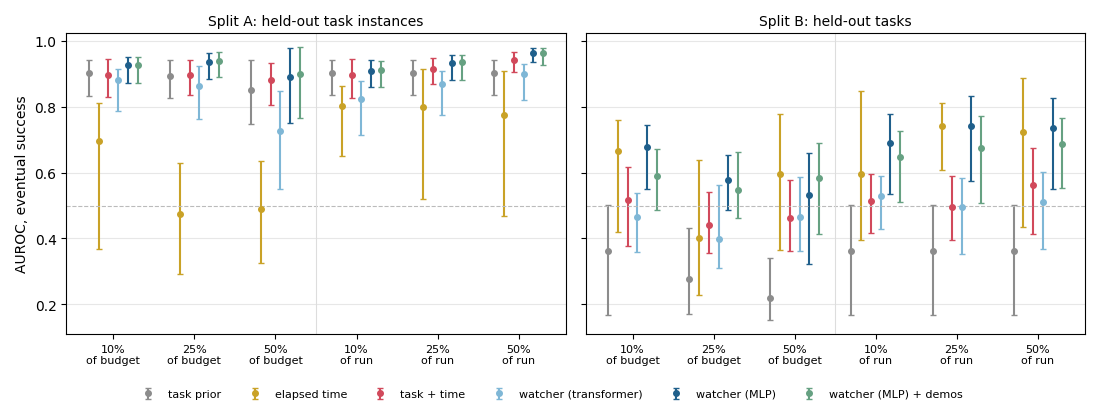
| MLP watcher | 0.92 | 0.94 | 0.89 |
| task plus time | 0.89 | 0.90 | 0.88 |
| task prior alone | 0.90 | 0.89 | 0.85 |
The paired differences against task plus time are +0.03, +0.04 and +0.01, with task-bootstrap CIs that include zero. AUPRC is higher for the watcher, 0.37 against 0.19 at 10% of the budget, with a base rate of 0.045.
Held-out tasks
| predictor | 10% | 25% | 50% |
|---|---|---|---|
| MLP watcher | 0.68 | 0.58 | 0.53 |
| elapsed time alone | 0.67 | 0.40 | 0.60 |
Notes
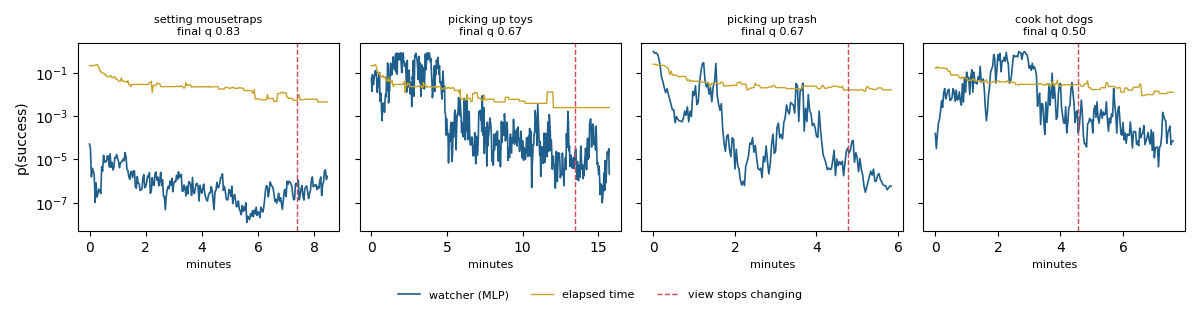
Adding the 1,000 teleop demos changes nothing on held-out instances and slightly hurts held-out tasks. Scoring at a fraction of each run's own length leaks the outcome, because successes end early, so only the fraction-of-budget numbers are honest. The watcher score falls before the view freezes on most failed runs, but the curve is noisy, so this is weak evidence for an early alarm.
Next steps would be dense q labels, patch tokens or fine-tuning instead of the pooled SigLIP output, and successes from more tasks.