OpenVLA language ablation on LIBERO-Goal: results
Full sweep, 800 episodes, NCSA DeltaAI GH200, Oct 20, 2026
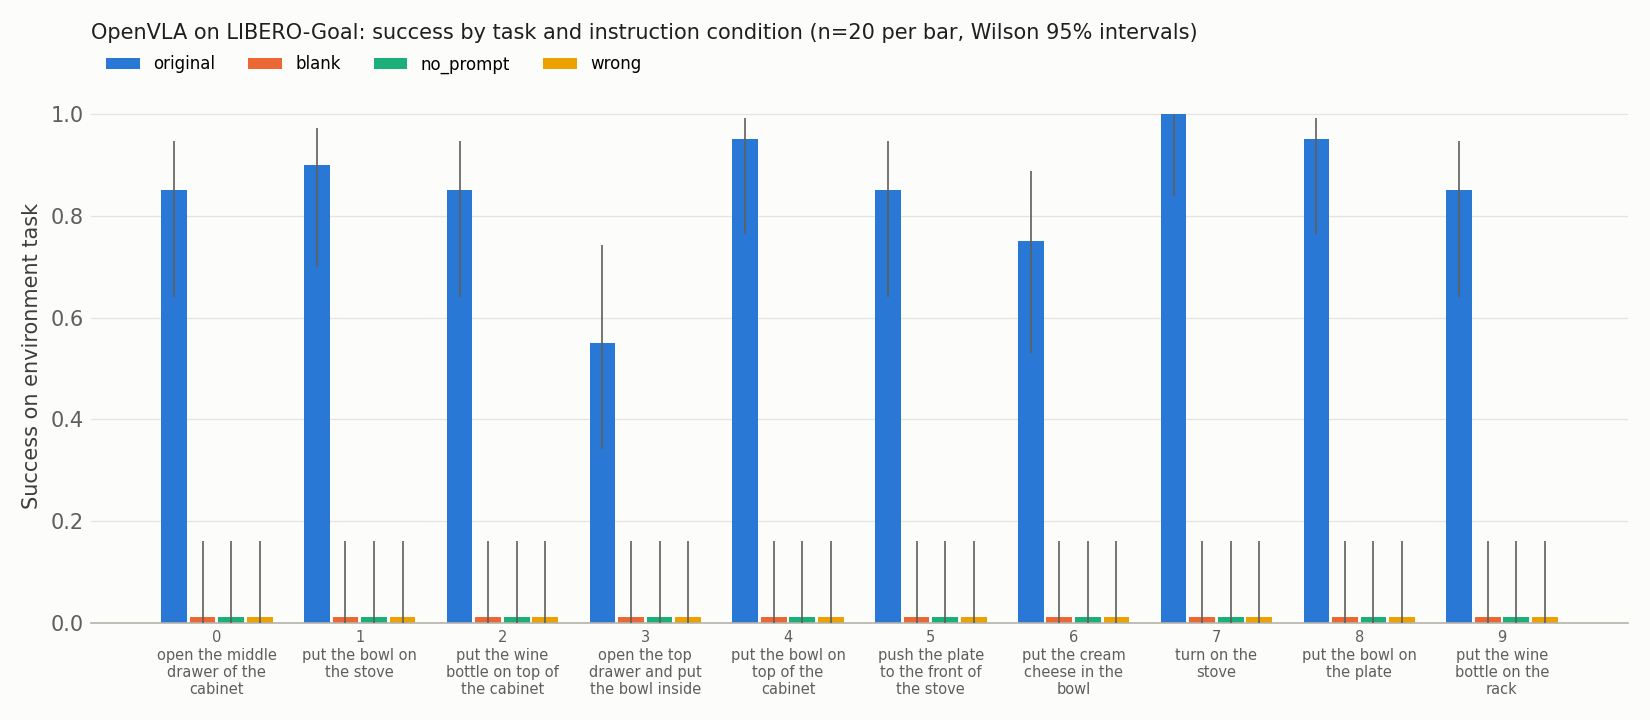
With the original instruction the fine-tuned OpenVLA succeeds on 170 of 200 LIBERO-Goal episodes (85.0%). With a blank instruction, no prompt at all, or the instruction of a different task, it succeeds on 0 of 200 each. Given the wrong instruction it carries out the commanded task instead in 148 of 200 episodes (74.0%). The policy takes its goal from the words, not from the scene. The pilot checked the pipeline first.
Setup
- Checkpoint openvla/openvla-7b-finetuned-libero-goal (snapshot fa5ae1e) as released, inference only, bf16, no quantization, greedy decoding.
- 10 tasks by 4 conditions by 20 episodes = 800 episodes. Episode k of every condition uses LIBERO init state k, seed 7, the same center crop, 300 max steps plus 10 wait steps and the libero_goal un-normalization key, so the conditions are paired episode by episode.
- The official run_libero_eval.py with a small patch: an instruction-mode flag, prompt construction per mode, per-task sharding, a resumable per-episode JSONL log, a reseed at the start of every episode, and scoring of the commanded task with LIBERO's own BDDL goal predicates.
- Hardware: every episode ran on NVIDIA GH200 120GB at NCSA DeltaAI, 2 eval processes per GPU.
- Reference: the OpenVLA paper reports 79.2 ± 1.0% on LIBERO-Goal (A100, 3 seeds of 500 episodes).
Prompts
Every condition sees the same image with the same model. Only the text prompt changes. predict_action appends token 29871 to every prompt before generating actions.
| condition | prompt string (task 0) | what changes |
|---|---|---|
| original | In: What action should the robot take to open the middle drawer of the cabinet?\nOut: | nothing, the task's own instruction |
| blank | In: What action should the robot take to ?\nOut: | empty instruction in the same template |
| no_prompt | In: \nOut: | no template and no instruction |
| wrong | In: What action should the robot take to put the bowl on the stove?\nOut: | task i gets the instruction of task (i+1) mod 10 |
Success on the environment's task
| condition | successes | rate | Wilson 95% interval |
|---|---|---|---|
| original | 170/200 | 85.0% | 79.4% to 89.3% |
| blank | 0/200 | 0.0% | 0.0% to 1.9% |
| no_prompt | 0/200 | 0.0% | 0.0% to 1.9% |
| wrong | 0/200 | 0.0% | 0.0% to 1.9% |
The paper reports 79.2 ± 1.0% for LIBERO-Goal. Our 85.0% is slightly higher, and the paper's 79.2% falls just below our interval. That is consistent with using one seed and only init states 0 to 19 (see the caveats). The checkpoint reproduces the paper's level.
Per task
| task | instruction | original | blank | no_prompt | wrong |
|---|---|---|---|---|---|
| 0 | open the middle drawer of the cabinet | 17/20 | 0/20 | 0/20 | 0/20 |
| 1 | put the bowl on the stove | 18/20 | 0/20 | 0/20 | 0/20 |
| 2 | put the wine bottle on top of the cabinet | 17/20 | 0/20 | 0/20 | 0/20 |
| 3 | open the top drawer and put the bowl inside | 11/20 | 0/20 | 0/20 | 0/20 |
| 4 | put the bowl on top of the cabinet | 19/20 | 0/20 | 0/20 | 0/20 |
| 5 | push the plate to the front of the stove | 17/20 | 0/20 | 0/20 | 0/20 |
| 6 | put the cream cheese in the bowl | 15/20 | 0/20 | 0/20 | 0/20 |
| 7 | turn on the stove | 20/20 | 0/20 | 0/20 | 0/20 |
| 8 | put the bowl on the plate | 19/20 | 0/20 | 0/20 | 0/20 |
| 9 | put the wine bottle on the rack | 17/20 | 0/20 | 0/20 | 0/20 |
| all | 10 tasks | 170/200 | 0/200 | 0/200 | 0/200 |
Paired McNemar test against original
| condition | pairs | original only | condition only | both | neither | exact p |
|---|---|---|---|---|---|---|
| blank | 200 | 170 | 0 | 0 | 30 | 1.3e-51 |
| no_prompt | 200 | 170 | 0 | 0 | 30 | 1.3e-51 |
| wrong | 200 | 170 | 0 | 0 | 30 | 1.3e-51 |
Wrong instruction: scene or words?
Under the wrong condition the scene is built for task i while the prompt asks for task (i+1) mod 10. The patched evaluator checks both goals at every step.
| commanded task done | commanded task not done | |
|---|---|---|
| environment task done | 0 | 0 |
| environment task not done | 148 | 52 |
The commanded task was reached in 148 of 200 episodes (74.0%, Wilson 95% interval 67.5% to 79.6%), close to the 85.0% the model gets when that same instruction is the correct one. No commanded goal was already true during the 10 wait steps (the preflight check over 50 init states is all zeros, and so are the Phase 2 episodes), so these are goals the policy achieved. The median first env step at which the commanded goal held is 103 (range 75 to 245), similar to the 108-step median of successful original episodes.
| env task | commanded task | commanded done | original success on the commanded task |
|---|---|---|---|
| 0 | 1 (put the bowl on the stove) | 19/20 | 18/20 |
| 1 | 2 (put the wine bottle on top of the cabinet) | 18/20 | 17/20 |
| 2 | 3 (open the top drawer and put the bowl inside) | 7/20 | 11/20 |
| 3 | 4 (put the bowl on top of the cabinet) | 18/20 | 19/20 |
| 4 | 5 (push the plate to the front of the stove) | 15/20 | 17/20 |
| 5 | 6 (put the cream cheese in the bowl) | 14/20 | 15/20 |
| 6 | 7 (turn on the stove) | 17/20 | 20/20 |
| 7 | 8 (put the bowl on the plate) | 16/20 | 19/20 |
| 8 | 9 (put the wine bottle on the rack) | 11/20 | 17/20 |
| 9 | 0 (open the middle drawer of the cabinet) | 13/20 | 17/20 |
| all | 10 tasks | 148/200 | 170/200 |
Interpretation
In LIBERO-Goal all 10 tasks share one scene layout, so the image cannot say which task to do. The model's behavior is set by the instruction. With no usable instruction (blank or no_prompt) it never completes any task. With a swapped instruction it carries out the swapped task about as often as it does when that instruction is correct, and never the task the episode was built for. The fine-tuned policy reads the goal from language. It is not solving the task from visual context alone.
Clips
Episode 0 of three tasks under all four conditions, agent-view camera at 224 by 224, 30 fps. Behavior descriptions are by eye. The wrong clips show episodes where the commanded task was done.
Task 1, put the bowl on the stove
Task 6, put the cream cheese in the bowl
Task 8, put the bowl on the plate
Caveats
- n=20 per cell. Per-task intervals are wide (for example task 3, 11/20, Wilson 34% to 74%), so per-task differences are not resolved. The condition-level effects are far outside the noise.
- One seed (7) and init states 0 to 19 of the 50 LIBERO provides. The paper used 3 seeds by 50 init states.
- success_commanded_task records whether the commanded goal held at any step after reset. Wrong episodes always run the full 300 steps, so a goal reached and later undone still counts. success_env_task uses env.check_success, which ends the episode, as in the upstream script.
- blank and no_prompt failures are all or nothing, so this study does not show what those episodes did instead. Videos for episodes 0 and 1 of every cell were saved.
- Greedy decoding throughout, so the seed only affects the simulator, not the policy.
Deviations from the requested setup
- GPU: all runs on NVIDIA GH200 (NCSA DeltaAI, aarch64) instead of KOA A30. The KOA A30 queue estimated a November start. One GPU type was used for every episode.
- Software: NGC container nvcr.io/nvidia/pytorch:24.01-py3 with torch 2.2.0a0+81ea7a4 and Python 3.10.12 (pinned PyPI torch 2.2.0 has no CUDA aarch64 wheel), flash-attn 2.5.5 built from source, a tensorflow 2.15 CPU build, opencv-python-headless, and tensorflow_graphics without tensorflow-addons (training only).
- mujoco 3.1.6 instead of the 3.16.0 that pip resolved. robosuite 1.4.1 fails an assert at env creation under 3.16.0, so the KOA env as built would also have failed.
- numpy pinned to 1.26.4 and tensorflow-metadata to 1.17.1, because the unpinned LIBERO requirements pulled numpy 2.x and a protobuf incompatible with TF 2.15.
- EGL: Ubuntu 22.04 glvnd libraries bound into the container. Rendering on EGL device 0 of the GH200 node aborted after 25 to 50 model queries, so workers on GPU 0 render on GPU 1's EGL device. Model inference is unchanged.
- 2 eval processes per GPU (8 per node). This only affects wall time. Mean inference latency is 0.257 s per step.
- The model loads through the checkpoint's Hugging Face remote code (OpenVLAForActionPrediction from openvla/openvla-7b), as on any standard setup.
- The eval patch reseeds (set_seed_everywhere) at the start of every episode so episode k is identical across conditions and resumable shards. Upstream seeds once per run.
- TF_FORCE_GPU_ALLOW_GROWTH=true so TensorFlow image ops do not reserve GPU memory.
Compute
Phase 2 ran in three 1-hour jobs on one 4-GPU node (jobs 3425917, 3426272 and 3427020), from 15:35 to 19:23 HST on Oct 20. Mean episode wall time was 75.4 s: 41.6 s for original and about 87 s for the other conditions, which always run to 300 steps. That is about 20 GPU-hours for Phase 2 and 32 for the whole study.